Capacity planning is not only about how many transfers are processed in a month. It is about whether the platform can keep processing them reliably during peak periods while compliance, payouts, and operational controls remain stable.
For a growing MTO, transaction volume is not only the number of transfers processed in a day. It is also a measure of whether the platform can keep accepting, validating, screening, paying out, and reconciling transactions as the business expands.
When customer demand rises, corridors expand, and payout methods diversify, the platform needs to process more transactions without creating delays in onboarding, KYC, sanctions screening, FX calculations, payment execution, or payout handling. That is what transaction throughput measures.
In This Article
Suppose a remittance platform has a theoretical throughput of 100 transactions per second. That sounds impressive, but it does not automatically mean an MTO can safely process 100 completed transfers every second.
Why? Because one customer transaction can trigger multiple downstream steps. A single transfer may involve customer initiation, KYC checks, sanctions screening, risk evaluation, payment execution, FX calculation, transaction processing, payout instruction, reconciliation, and audit logging.
The infrastructure may therefore handle many more technical events than the number of customer-visible transfers. This is why an MTO should ask what the quoted throughput metric actually represents.
Review how throughput, partner routing, and compliance checks work together in a high-volume remittance platform.
Explore Platform FeaturesAt low transaction volumes, a few seconds of delay may not matter much. But when an MTO is processing thousands of transfers a day, the same delay can create queue pressure, operational friction, and growing support overhead.
Growth often increases several workloads at once: more customers, more KYC checks, more sanctions screening, more FX calculations, more payout requests, more database writes, and more monitoring events. The result is that a platform can remain available while quietly becoming slower than the business requires.
As noted in infrastructure reliability article, scaling is not only about adding volume; it is about maintaining predictable service while operational complexity rises.
One common mistake is to multiply theoretical TPS by the number of seconds in a day and assume that is a realistic daily capacity. A number like 100 TPS × 86,400 seconds may look enormous, but in practice it is a best-case mathematical maximum under ideal conditions.
Real remittance activity is uneven. Some periods are quiet; others are crowded. A platform should therefore be evaluated on at least three measurements:
| Metric | What it tells the MTO |
|---|---|
| Average throughput | Normal transaction-processing rate across a day or period. |
| Peak throughput | Maximum expected volume during a short burst or campaign-driven period. |
| Sustained throughput | Whether the platform can maintain performance over a longer time without degradation. |
For an MTO, the combination of these measurements is more useful than a single headline number. A platform with a high peak benchmark but weak sustained performance may still create operational problems.
Many MTOs see short bursts of higher volume rather than a steady daily flow. Payroll cycles, festivals, corridor surges, marketing campaigns, and delay-driven catch-up periods can create temporary peaks. If the platform was sized around average usage alone, it may struggle when volume suddenly rises.
That is why MTOs should ask providers about peak TPS, burst handling, queue management, automatic scaling, and failure recovery behavior. The goal is not simply to display a big number; it is to maintain predictable processing when the business enters a busy period.
A remittance platform cannot treat throughput as a purely technical metric. Every transaction can generate additional compliance and operational work. A platform processing thousands of transfers may also need to run checks for customer due diligence, sanctions exposure, risk thresholds, and transaction monitoring rules.
If compliance workflows cannot keep up with transaction processing, the business may experience the wrong kind of scaling: faster transfer creation but slower compliance review. For an MTO, that is not true scalability.
That is why throughput should be evaluated across the entire transaction lifecycle, including KYC, sanctions, risk, monitoring, and reporting. FATF guidance and risk-based controls place operational discipline around these processes; they are not optional afterthoughts.
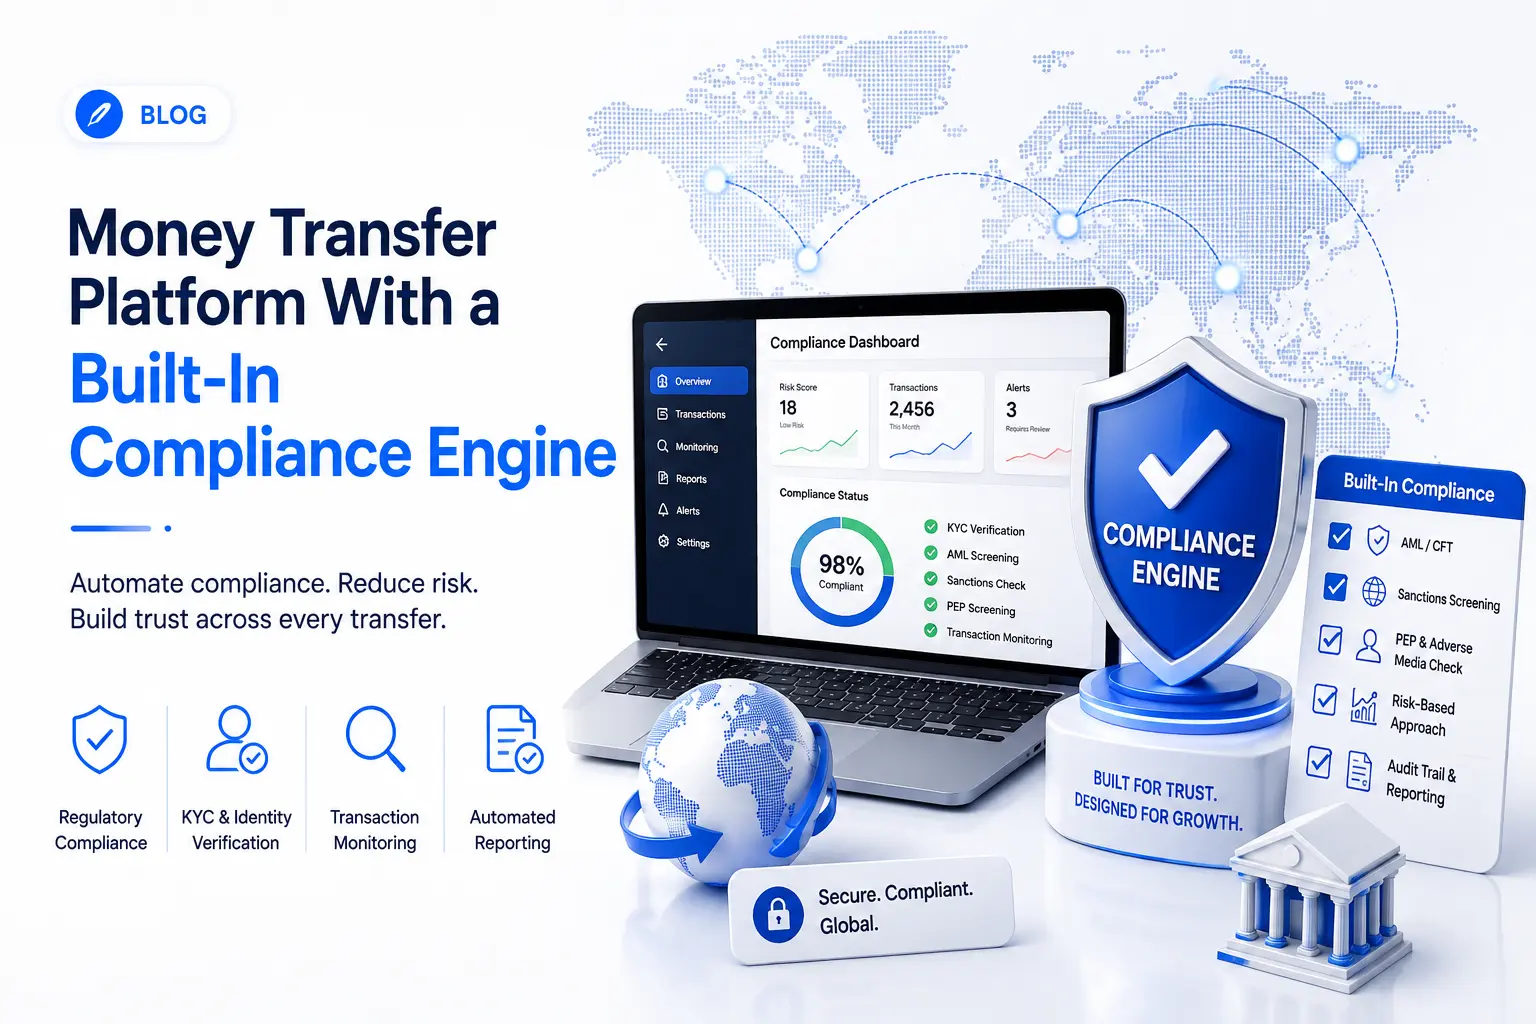
For teams building a more resilient compliance layer, the related article on money transfer platform compliance engines is a practical next step.
Bottlenecks do not always show up as full outages. More often, they surface as slower APIs, delayed status updates, increasing queue lengths, longer compliance reviews, payout delays, or a higher volume of support tickets.
This can be worse than a sudden outage because the symptoms are less obvious. A platform may still appear online while the business becomes operationally constrained behind the scenes.
Watch queue pressure, payout delays, and compliance backlogs as early indicators that your platform is reaching its sustainable limit.
Request a DemoAn MTO should not only ask, "How many transactions per second can your API handle?" A better question is: "How does the platform perform across the full transaction lifecycle?"
| Stage | What to evaluate |
|---|---|
| Customer onboarding | Concurrent registration and KYC activity. |
| Compliance | Bottlenecks in sanctions, AML, and transaction-monitoring checks. |
| Payment | Processing speed for payment requests and transaction creation. |
| FX and pricing | Rate calculation and quote response performance. |
| Monitoring | Operational visibility and rule-engine performance. |
| Payouts | Partner routing, payout status updates, and settlement visibility. |
| Reporting | Reconciliation, settlement, and business-intelligence workloads. |
An MTO can estimate demand before choosing infrastructure. A simple model looks like this:
Step 1: Estimate daily transaction volume.
Step 2: Identify the busiest operational window.
Step 3: Estimate peak volume during that window.
Step 4: Add a burst factor based on seasonality or corridor growth.
Step 5: Validate whether the infrastructure can handle both average and peak loads without slowing compliance workflows.
For instance, if an MTO expects 30,000 transactions a day and 40% of activity arrives within an 8-hour period, the busy window may require a much higher processing rate than a simple daily average suggests. That is the real planning problem.
Start with average, peak, and sustained load so capacity planning reflects normal and stressed conditions.
Fast payment processing matters only when KYC, sanctions, and monitoring stay responsive too.
Functional processing is not enough if partner routing, status updates, and retries fail under load.
Choose a remittance platform that can handle transaction spikes, compliance checks, and payout operations without creating operational bottlenecks.
Request a Demo Explore FeaturesIt is the amount of transaction activity a platform can process during a specified period, usually measured in transactions per second or per day.
Busy periods often create short-term surges. If infrastructure is sized only for average activity, transaction queues and processing delays can appear quickly.
Not necessarily. An MTO should evaluate throughput alongside latency, compliance processing capacity, payout reliability, and peak-load performance.
They should estimate regular transaction volume, peak periods, corridor expansion, and compliance-processing load, then validate the full transaction lifecycle rather than a single benchmark.